By the numbers
- bills ingested
- 167k+
- AI analyses written
- 29k+
- faster vector search
- ~220×
- missing historical bills recovered
- 8,300+
Overview
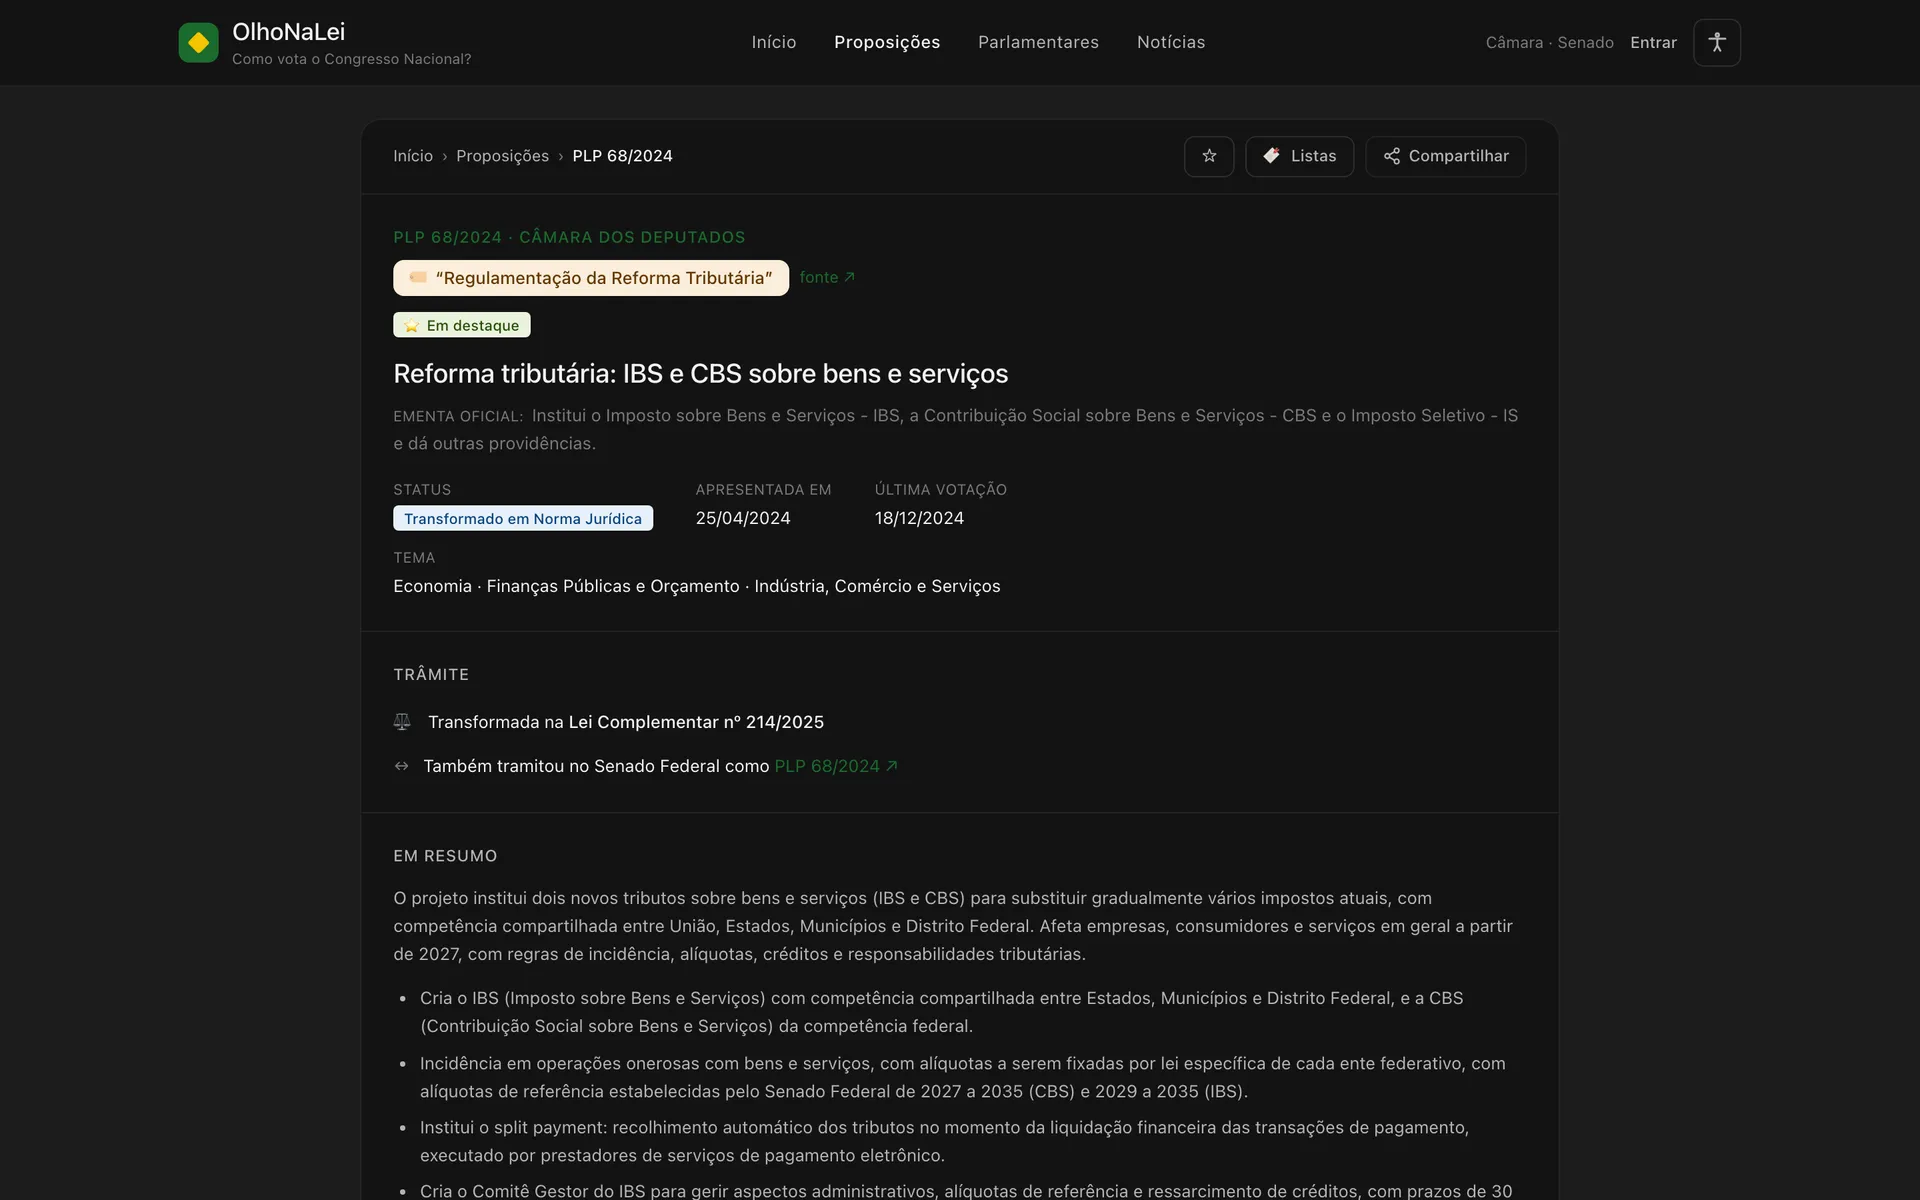
OlhoNaLei puts in one place what happens in Brazil's Chamber of Deputies and Senate: bills in progress, how each vote ended and how each member of Congress voted, with plain-language AI summaries. Data comes from the two houses' official open-data portals.
I designed, built and operate it alone, from the ingestion pipeline to the pixels. It is live and in low-maintenance mode.
Independent and nonprofit: it is not a government service and has no link to any party or public body.
How the data flows
Sources
Chamber API
Senate API
Ingestion
Python pipeline
nightly · resumable · idempotent
Staging
Firestore
write-only
Store
PostgreSQL + pgvector
Supabase, São Paulo
AI analysis
Claude Message Batches
monthly budget caps
Delivery
Next.js site + admin
Search Edge Function
Social + newsletter
human review
What I built
- 01Designed, built and operate the whole platform alone: data pipeline, REST API, AI analysis, frontend, infrastructure and growth.
- 02Nightly, resumable, idempotent Python ingestion from the Chamber and Senate open-data APIs (Firestore staging → PostgreSQL), unifying two different JSON shapes into one relational model.
- 03Hybrid search (PostgreSQL full-text with the Portuguese dictionary + pgvector), rebuilt with binary quantization and reranking: ~1,850 ms → ~8 ms.
- 04Claude analysis pipeline: 29,000+ plain-language summaries, fiscal-impact assessments and legislative-rider (“jabuti”) detection, under monthly LLM budget caps with the Message Batches API.
- 05Public site and internal admin console in Next.js 15 / React 19 / TypeScript / Tailwind (Server Components, ISR, dynamic OG images).
- 06Automated distribution to Instagram, Facebook, Bluesky and a newsletter, with human-in-the-loop review.
- 07Diagnosed and eliminated a ~39,000-invocation serverless cost blowout.
- 08Security: row-level security, PostgREST and compliance with the LGPD, Brazil's data-protection law.
Before and after
- Before
- ~1,850 ms
- After
- ~8 ms (~220×)
- Before
- 1.3 GB
- After
- 69 MB
- Before
- ~1.49 s
- After
- ~0.55 s
Case studies
Making vector search 220× faster on a small Postgres
Problem
Hybrid search (full-text + pgvector) over 167k+ bills took ~1,850 ms per query, and the 1.3 GB HNSW index didn't fit comfortably in the memory of a budget Postgres instance.
What I did
- Profiled the query path before changing anything.
- Rebuilt the HNSW index with binary quantization: vectors stored as bits for a fast first pass, then the top candidates reranked with full-precision vectors to keep result quality.
- Benchmarked before and after.
- Then measured the rest of the end-to-end time: the API ran in the US while the database and the site were in São Paulo, so every search crossed the equator three times (184 ms per hop, for 18 ms of actual Postgres work).
- Moved search to a Supabase Edge Function in the database's region, with cached query embeddings, a one-variable rollback to the old path, and an explicit lexical fallback (busca_degradada: true) so silent degradation shows up.
Result
Index 1.3 GB → 69 MB. Database search ~1,850 ms → ~8 ms (~220×). End-to-end search in production ~1.49 s → ~0.55 s.
Lesson
Performance measured, not guessed.
Cost-governed AI at scale
Problem
Write useful, plain-language analysis for tens of thousands of bills without an open-ended LLM bill.
What I did
- A Claude pipeline on the Message Batches API, which is cheaper and asynchronous.
- Monthly budget quotas enforced in code. The backfill is budget-gated and resumable: it stops at the cap and continues next month without losing work.
- Each analysis covers a plain-language summary, the fiscal impact and possible “jabutis”: Brazilian slang for an unrelated provision slipped into a bill, like a legislative rider (“a tortoise doesn't climb a tree by itself”). Flagged bills get a badge on the site.
- Posts to Instagram, Facebook, Bluesky and the newsletter go through human review.
Result
29,000+ analyses with predictable spend. Separately, I found and eliminated a ~39,000-invocation serverless cost blowout.
Lesson
Cost is a feature.
Two government APIs, one data model
Problem
The Chamber and the Senate publish legislation through two very different flat JSON APIs.
What I did
- A nightly Python pipeline that is resumable, checkpointed and idempotent: retries never duplicate or lose records.
- Raw data is staged in Firestore (write-only), then normalized into one relational PostgreSQL model: bills, authors, votes and members of Congress.
- The product never calls a government API at request time; everything is served from PostgreSQL.
- Structured logs throughout.
Result
167,000+ bills in one model, and 8,300+ missing historical bills recovered by a budget-gated backfill.
Architecture decisions
ADR 01
No live government API calls at request time: all data is pre-ingested and served from PostgreSQL.
ADR 02
Firestore is a write-only staging layer; the product API reads only from PostgreSQL.
ADR 03
PostgreSQL full-text search with the Portuguese dictionary.
ADR 04
Semantic search runs in a Supabase Edge Function in São Paulo (sa-east-1), next to the database.
Stack
- Python
- FastAPI
- Next.js 15
- React 19
- TypeScript
- Tailwind CSS
- PostgreSQL
- pgvector
- Supabase
- Deno Edge Functions
- Firestore
- Voyage embeddings
- Claude Message Batches
- Railway
- Vercel
- GitHub Actions
- Sentry